UltraSenSync™AI Video Co-Pilot & Hybrid Reasoning Pipeline
A breakthrough that brings vision-language models (VLM Reasoning) directly into video security. Query 160 AI camera streams in natural Vietnamese with response latency under 10 seconds.
Warehouse B Camera - Door 2 (14:32:15): Yellow forklift carrying a pallet detected; the driver wears an orange safety vest and is moving from Workshop 1 to the Packaging Workshop.
Hybrid Edge-Central Pipeline
How TNT Technologies solves the cost problem: heavy detection runs at the network edge, and deep contextual reasoning runs only on the Top-K most promising candidates at the central server.
1. Edge Perception
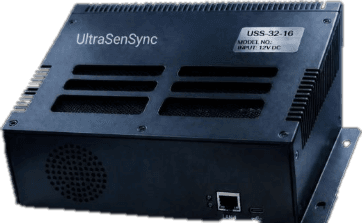
Each distributed NVIDIA Jetson box ingests 16 real-time camera channels, extracts detections (people, vehicles, objects, behavior), and stores original video locally (3.2 TB), cutting WAN traffic by 95%.
2. Fast Hybrid Retrieval
The central server indexes vectors and structured metadata (time, clothing color, zone, duration), returning 50–200 matching candidate clips in under 1 second.
3. VLM Reasoning Reranking
The vision-language model (Qwen3-VL / GLM-V) activates only to “watch” the Top-5 most promising clips, verifies the evidence, and returns a logical explanation in Vietnamese.
UltraSenSync System Specifications
| Parameter | Standard configuration | Business value |
|---|---|---|
| Edge AI Hardware | 10× NVIDIA Jetson AI Boxes (Orin / AGX Orin) | Distributed on-site processing with industrial 24/7 stability |
| Camera scale | 160 AI Streams + 320 Recording Channels | Full coverage of a 50,000 m² factory |
| Edge storage capacity | 3.2 TB NVMe SSD per box (32 TB per cluster) | 30-90 days of Full HD video stored on-site |
| Semantic query latency | Under 10 seconds (cross-camera search) | Cuts incident footage retrieval time by 99% |
| Central Server | Single RTX 4090 (24GB VRAM) / 10 GbE LAN | Saves 80% on server hardware investment |
| Security & data sovereignty | 100% On-Premise (Private Network) | No data sent to foreign clouds; ISO 27001 aligned |
Ready to upgrade your cameras with UltraSenSync™?
TNT Technologies engineers are ready to survey your camera infrastructure and run a pilot PoC within 48 hours.